Most Farm Trials End in an Argument
A grower tries something new on one row, the neighbouring row looks different three weeks later, and nobody can say whether it was the change, the position in the house, or the week the vents were stuck. Everyone has an opinion and no one has an answer. Repeat that twice and the farm stops experimenting altogether, which is worse.
Hydroponic trial design does not need to be academic. It needs three things most informal trials lack: replication, a control block running at the same time, and a decision rule agreed before the first measurement.
Why Position Beats Treatment in Most Poor Trials
| Confounder | How it distorts results | How to control it |
|---|---|---|
| House position | Ends, edges and door zones differ in temperature and airflow | Replicate across positions rather than using one block per treatment |
| Irrigation zone boundaries | Emitting and return conditions vary by zone | Keep treatments inside a single zone, or replicate zones |
| Lighting gradient | Tiers and positions differ in light received | Randomise or alternate positions across the known gradient |
| Time of harvest | Grading and packing conditions shift through the day | Standardise harvest timing or record it for every plot |
| Operator effects | Different crews handle rows differently | Allocate work randomly, not by block |
| Seed lot differences | Batches differ more than treatments sometimes do | Use one seed lot, and record it |
The point of replication is to average those differences out. One row per treatment does not replicate anything — it compares two specific positions, which is a separate question nobody asked.
A Minimal Viable Design
- State the question in one sentence with a measurable outcome attached to it
- Pick one variable — everything else stays identical, including management
- Choose plot size that is realistic to measure, not convenient to find
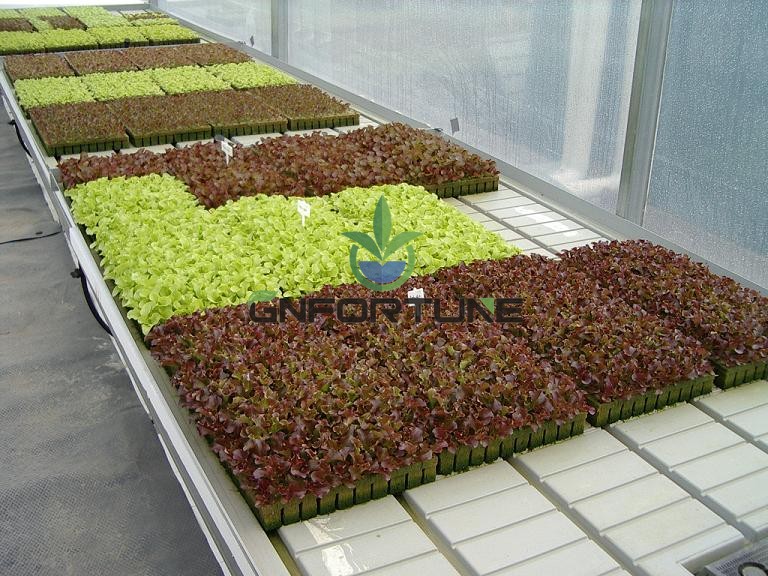
- Replicate at least three times, spread across the house rather than side by side
- Include the control running simultaneously, not a historical average
- Randomise assignment where you can, or use a systematic alternating pattern where you cannot
- Define measurements, method and frequency before starting
- Agree the decision rule: what difference would justify changing practice
- Write it all down and walk the crew through it once
Choosing What to Measure
| Aim | Primary measurement | Also worth capturing |
|---|---|---|
| Higher output | Saleable weight per square metre | Size distribution, reject categories |
| Better quality | Grade-out rate by defect type | Shelf-life scores where relevant |
| Lower cost | Labour minutes per unit produced | Consumables, energy per unit |
| Disease reduction | Incidence by plot and date | Climate records during the same period |
| Nutrition change | Yield plus sap and tissue results | Discharge volumes, EC behaviour |
Measure the thing you are trying to change, plus whatever that change could plausibly damage. A density trial that only measures yield will recommend a density that wrecks your labour budget.
Measurement Cost Is Real
- Every extra measurement costs labour — and in a trial, that labour often comes from the same crew doing production work
- Destructive measurements remove saleable product; budget for it explicitly
- Instrumented measurements require calibration and someone competent to install them
- Poor measurements are worse than fewer. A noisy dataset cannot answer a small question, whatever the spreadsheet says afterwards
- Repeated measures over time usually beat a single large destructive harvest for steering decisions
Reading Results Without Fooling Yourself
- Look at variation between replicates before celebrating an average difference
- Small differences need more replication, not more confidence
- Repeated consistent direction across measures is more convincing than one big number
- Practical significance beats statistical significance. A 2 percent yield gain may be real and still not worth the operational change
- Repeat across a second cycle or season before rolling a result out across the farm
- Write down what happened to the control too — it explains whether the season itself was unusual
Trials That Work on Real Farms
| Question | Practical design | Measured outcome |
|---|---|---|
| Tighter spacing pays? | Three blocks each at two spacings, randomised across the house | Saleable weight per square metre plus labour minutes |
| New variety better? | Adjacent blocks, same seed lot where possible, two seasons | Yield, grade-out and uniformity |
| Lower EC viable? | Split-zone trial with the same crop and management | Yield plus visual quality and any disorder scoring |
| New sanitiser effective? | Compare disease incidence against a control line | Incidence plus any crop response observation |
| Labour-saving tool? | Time the same task across comparable blocks repeatedly | Minutes per unit plus quality consequences |
Turning Results Into Practice
- Publish the result internally with the design and the numbers, even when it is inconclusive
- Roll out in stages rather than changing practice on the whole farm at once
- Keep monitoring for a further cycle to confirm the effect survives contact with a different season
- Build a trial calendar so that experimentation is planned into production rather than squeezed into it
- Keep the designs. A farm with five years of trial records has an advantage no equipment purchase can match
FAQ
How much replication do I really need?
At least three plots per treatment, and more when you are looking for small differences or when blocks vary substantially. Replication buys signal; without it you are measuring positions, not treatments.
Can I just compare this season to last season?
No. Weather, seed lots, crew, market specifications and pests all change between seasons. Historical comparison is a hypothesis generator, not evidence.
Is statistics software necessary?
Not for clear differences, but useful where effects are small. Simple checks — spread between replicates, consistency across measures — catch most false conclusions.
How long should a trial run?
At least one full crop cycle for most questions, and ideally across two seasons where the answer could be seasonal — which most are.
What if production gets in the way?
Plan it into the schedule and keep the plot size modest. A well-run small trial beats an ambitious one that nobody had time to measure.
How do I stop bias?
Agree the decision rule in writing before starting, and measure with the same method everywhere. Where possible, have someone who did not set up the trial do the measuring.
Set Up the Next Trial Properly
Layout and zone design make a trial easy or nearly impossible. If you are planning a house where you intend to experiment, tell us — we will lay out zones and measurement points accordingly. Start with the quote form.
Related reading: trials feed several decisions — see plant spacing and density, variety selection and seed sourcing, tissue and sap testing, staffing and training and scaling from pilot row to commercial.